Comparison · Anthropic and Z.ai
Claude Sonnet 5.5 vs GLM 5.3 Prime
Listed API prices of Claude Sonnet 5.5 and GLM 5.3 Prime turned into the cost of the same three standard tasks and what each provider’s API documentation says about features that break on a switch. Output quality, speed and answer length are not compared.
Calculated impact cost per task and per month
For an L2 task (deep analysis over a 50,000-token document, 3 steps), Claude Sonnet 5.5 costs $0.348 and GLM 5.3 Prime $0.472 at the prices listed in the United States on , so Claude Sonnet 5.5 is 26.2 % less than GLM 5.3 Prime, counting visible output only, without cache discounts or hidden reasoning.

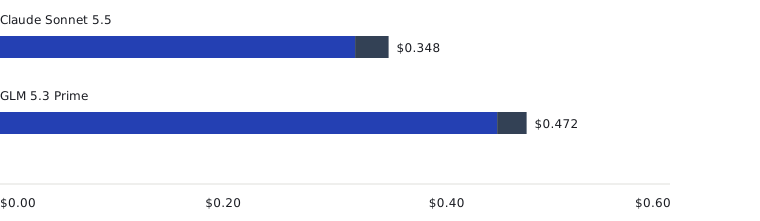
| Task | Claude Sonnet 5.5, per task | GLM 5.3 Prime, per task | Claude Sonnet 5.5, per month | GLM 5.3 Prime, per month | Claude Sonnet 5.5 vs GLM 5.3 Prime, per task |
|---|---|---|---|---|---|
| L1Micro-task (classification or strict JSON extraction) | $0.0050per L1 task | $0.0060per L1 task | $73.00per month | $87.02per month | −16.1 % |
| L2Deep analysis over a 50,000-token document | $0.348per L2 task | $0.472per L2 task | $5,080.80per month | $6,885.36per month | −26.2 % |
| L3Agentic coding loop, 15 steps | $2.72per L3 task | $3.76per L3 task | $39,726.60per month | $54,933.96per month | −27.7 % |
Calculated Per month: 20 tasks an hour around the clock, 730 hours.
Prices USD per 1M tokens
| Price | Claude Sonnet 5.5 | GLM 5.3 Prime |
|---|---|---|
| Input, per 1M tokens | $2.00 | $2.80 |
| Output, per 1M tokens | $10.00 | $8.80 |
| Price from | Provider's price list · source page Published | OpenRouter · source page (data) Published |
| Read | · the United States | · the United States |
| Context window | 1,000,000 tokens | 1,000,000 tokens |
What can I use it for? six common tasks, our data checks
Quality on your task: not measured by Measured Lab yet.
| Task | Claude Sonnet 5.5 | GLM 5.3 Prime |
|---|---|---|
| Answer customer messages | Fits on price and context | — |
| Pull data from invoices and documents with strict JSON and page images | Fits on price and context | — |
| Summarize documents and meetings | Fits on price and context | — |
| Translate content | Fits on price and context | — |
| Chat assistant on your website | Fits on price and context | — |
| Write and review code with tool calls | Fits on price and context | — |
| Tasks it fits | 6 of 6 | — |
Checks of our data for six common tasks: a published price, a context window and answer length for the task and, where the task needs them, strict JSON output, page images and tool calls; prices, cost a month and terms for each model on its model card. GLM 5.3 Prime is not in the model picker. Compare models for your own task in the model picker.
What breaks when you switch Published provider documentation
Moving from Anthropic to Z.ai, 4 of the 5 features may not carry over, by each provider’s documentation:
- Strict JSON schemas — Anthropic: yes; Z.ai: partly. Code that parses answers without checks starts failing where a provider promises only valid JSON, not your schema.
- Parallel tool calls — Anthropic: yes; Z.ai: not stated. An agent built around several calls per turn gets one call per turn: more round trips, more input tokens, slower runs.
- Streamed tool arguments — Anthropic: yes; Z.ai: partly. An interface that shows arguments as they are written sees nothing until the whole call is ready.
- Cache covers tool definitions — Anthropic: yes; Z.ai: not stated. Where the cache does not cover tool definitions, a long tool list is paid as fresh input on every request.
Moving from Z.ai to Anthropic: every feature that Z.ai’s documentation lists as supported is also listed as supported by Anthropic.
| Feature of the API | Anthropic | Z.ai |
|---|---|---|
| Strict JSON schemas | Yes | Partly |
| Parallel tool calls | Yes | Not stated |
| Streamed tool arguments | Yes | Partly |
| Reasoning with tools | Yes | Yes |
| Cache covers tool definitions | Yes | Not stated |
What each provider’s own API documentation says, read ; “not stated” is not the same as “no”. Quotes and sources: what breaks when you switch AI APIs.