Comparison · Qwen and Z.ai
Qwen3.8 27B vs GLM 5.3
Listed API prices of Qwen3.8 27B and GLM 5.3 turned into the cost of the same three standard tasks, with speed from our own test requests in the United States and what each provider’s API documentation says about features that break on a switch. Output quality and answer length are not compared.
Calculated impact cost per task and per month
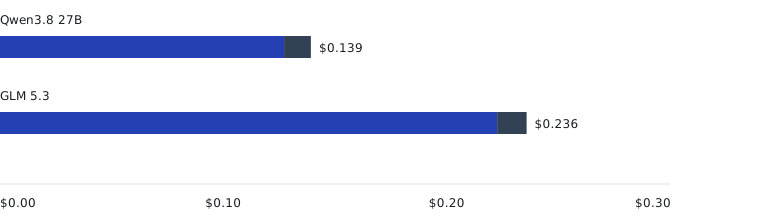
For an L2 task (deep analysis over a 50,000-token document, 3 steps), Qwen3.8 27B costs $0.139 and GLM 5.3 $0.236 at the prices listed in the United States on , so Qwen3.8 27B is 41.0 % less than GLM 5.3, counting visible output only, without cache discounts or hidden reasoning.

| Task | Qwen3.8 27B, per task | GLM 5.3, per task | Qwen3.8 27B, per month | GLM 5.3, per month | Qwen3.8 27B vs GLM 5.3, per task |
|---|---|---|---|---|---|
| L1Micro-task (classification or strict JSON extraction) | $0.0020per L1 task | $0.0030per L1 task | $29.20per month | $43.51per month | −32.9 % |
| L2Deep analysis over a 50,000-token document | $0.139per L2 task | $0.236per L2 task | $2,032.32per month | $3,442.68per month | −41.0 % |
| L3Agentic coding loop, 15 steps | $1.09per L3 task | $1.88per L3 task | $15,890.64per month | $27,466.98per month | −42.1 % |
Calculated Per month: 20 tasks an hour around the clock, 730 hours.
Prices USD per 1M tokens
| Price | Qwen3.8 27B | GLM 5.3 |
|---|---|---|
| Input, per 1M tokens | $0.800 | $1.40 |
| Output, per 1M tokens | $4.00 | $4.40 |
| Price from | Provider's price list · source page Published | Provider's price list · source page Published |
| Read | · the United States | · the United States |
| Context window | 1,024,000 tokens | 1,048,576 tokens |
What can I use it for? six common tasks, our data checks
Quality on your task: not measured by Measured Lab yet.
| Task | Qwen3.8 27B | GLM 5.3 |
|---|---|---|
| Answer customer messages | — | Fits on price and context |
| Pull data from invoices and documents with strict JSON and page images | — | Not confirmed: reads text only, per the OpenRouter listing |
| Summarize documents and meetings | — | Fits on price and context |
| Translate content | — | Fits on price and context |
| Chat assistant on your website | — | Fits on price and context |
| Write and review code with tool calls | — | Fits on price and context |
| Tasks it fits | — | 5 of 6 |
Checks of our data for six common tasks: a published price, a context window and answer length for the task and, where the task needs them, strict JSON output, page images and tool calls; prices, cost a month and terms for each model on its model card. Qwen3.8 27B is not in the model picker. Compare models for your own task in the model picker.
Speed in the US Observed our test requests
In our test requests from the United States, the median time to the first answer token was 139 ms for Qwen3.8 27B (Hosted by Cerebras) and 1,934 ms for GLM 5.3 (Direct API · Z.ai).
| Model and route | Time to first answer token, median | Output speed, median | Answers |
|---|---|---|---|
| Qwen3.8 27BHosted by Cerebras | 139 ms range 98 ms–16,848 ms | 610 tokens/s range 199 tokens/s–627 tokens/s | 115 answers on 23 dates |
| Qwen3.8 27BHosted by Groq | 195 ms range 102 ms–1,095 ms | 494 tokens/s range 210 tokens/s–528 tokens/s | 115 answers on 23 dates |
| GLM 5.3Direct API · Z.ai | 1,934 ms range 849 ms–7,367 ms | 70.7 tokens/s range 26.8 tokens/s–471 tokens/s | 114 answers on 23 dates |
| GLM 5.3OpenRouter → Z.AI | 2,191 ms range 1,092 ms–32,480 ms | 69.7 tokens/s range 22.8 tokens/s–610 tokens/s | 115 answers on 23 dates |
The same short request to every model, sent from a measurement point in the United States; medians of successful answers on at least 2 different dates, latest on . How we measure
What breaks when you switch Published provider documentation
Moving from Qwen to Z.ai, 1 of the 5 features may not carry over, by each provider’s documentation:
- Parallel tool calls — Qwen: yes; Z.ai: not stated. An agent built around several calls per turn gets one call per turn: more round trips, more input tokens, slower runs.
Moving from Z.ai to Qwen: every feature that Z.ai’s documentation lists as supported is also listed as supported by Qwen.
| Feature of the API | Qwen | Z.ai |
|---|---|---|
| Strict JSON schemas | Partly | Partly |
| Parallel tool calls | Yes | Not stated |
| Streamed tool arguments | Not stated | Partly |
| Reasoning with tools | Yes | Yes |
| Cache covers tool definitions | Not stated | Not stated |
What each provider’s own API documentation says, read ; “not stated” is not the same as “no”. Quotes and sources: what breaks when you switch AI APIs.
Price changes in the last 30 days
- The listed price of Qwen3.8 27B changed on on OpenRouter: input $0.24 → $0.04, output $2.20 → $1.35 per 1M tokens.
- The listed price of Qwen3.8 27B changed on on OpenRouter: input $0.04 → $0.20, output $1.35 → $2.50 per 1M tokens.
- The listed price of Qwen3.8 27B changed on on OpenRouter: input $0.20 → $0.04, output $2.50 → $1.25 per 1M tokens.
- The listed price of Qwen3.8 27B changed on on OpenRouter: input $0.04 → $0.15, output $1.25 → $1.88 per 1M tokens.
- The listed price of GLM 5.3 changed on on OpenRouter: output $4.80 → $1.40 per 1M tokens. Briefing
- The listed price of GLM 5.3 changed on on OpenRouter: input $0.08 → $0.07 per 1M tokens. Briefing