Comparison · Qwen

Qwen3.8 Max (0902) vs Qwen3.8 Max Prime

Listed API prices of Qwen3.8 Max (0902) and Qwen3.8 Max Prime turned into the cost of the same three standard tasks. Output quality, speed and answer length are not compared.

Calculated impact cost per task and per month

For an L2 task (deep analysis over a 50,000-token document, 3 steps), Qwen3.8 Max (0902) costs $0.336 and Qwen3.8 Max Prime $0.672 at the prices listed in the United States on , so Qwen3.8 Max (0902) is 50.0 % less than Qwen3.8 Max Prime, counting visible output only, without cache discounts or hidden reasoning.

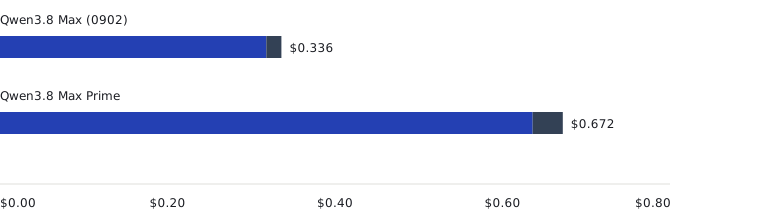
Head to head: Qwen3.8 Max (0902): $0.336; Qwen3.8 Max Prime: $0.672 Calculated from published rates Input and visible output are priced separately for the same task. 159,000 input + 3,000 visible output tokens per task. No cache discount; hidden reasoning excluded.
Head to head.Calculated from published rates Input and visible output are priced separately for the same task. 159,000 input + 3,000 visible output tokens per task. No cache discount; hidden reasoning excluded. Open image · Explore the chart · Measured Lab · CC BY 4.0
TaskQwen3.8 Max (0902), per taskQwen3.8 Max Prime, per taskQwen3.8 Max (0902), per monthQwen3.8 Max Prime, per monthQwen3.8 Max (0902) vs Qwen3.8 Max Prime, per task
L1Micro-task (classification or strict JSON extraction)$0.0042per L1 task$0.0084per L1 task$61.32per month$122.64per month−50.0 %
L2Deep analysis over a 50,000-token document$0.336per L2 task$0.672per L2 task$4,905.60per month$9,811.20per month−50.0 %
L3Agentic coding loop, 15 steps$2.69per L3 task$5.37per L3 task$39,201.00per month$78,402.00per month−50.0 %

Calculated Per month: 20 tasks an hour around the clock, 730 hours.

Prices USD per 1M tokens

PriceQwen3.8 Max (0902)Qwen3.8 Max Prime
Input, per 1M tokens$2.00$4.00
Output, per 1M tokens$6.00$12.00
Price fromProvider's price list · source page PublishedOpenRouter · source page (data) Published
Read · the United States · the United States
Context window1,000,000 tokens1,000,000 tokens

What can I use it for? six common tasks, our data checks

Quality on your task: not measured by Measured Lab yet.

TaskQwen3.8 Max (0902)Qwen3.8 Max Prime
Answer customer messagesFits on price and context—
Pull data from invoices and documents with strict JSON and page imagesFits on price and context—
Summarize documents and meetingsFits on price and context—
Translate contentFits on price and context—
Chat assistant on your websiteFits on price and context—
Write and review code with tool callsFits on price and context—
Tasks it fits6 of 6—

Checks of our data for six common tasks: a published price, a context window and answer length for the task and, where the task needs them, strict JSON output, page images and tool calls; prices, cost a month and terms for each model on its model card. Qwen3.8 Max Prime is not in the model picker. Compare models for your own task in the model picker.

All model comparisons · How we check prices

Explore the numbers

Calculated from published rates

The same work. Two bills.

Input and visible output are priced separately for the same task.

$0.336L2 task differenceQwen3.8 Max Prime more
$4,905.60L2 monthly differenceAssumption: 20 tasks/hour × 730 hours
Qwen3.8 Max (0902)$0.336Qwen3.8 Max Prime$0.672$0.00$0.20$0.40$0.60$0.80Qwen3.8 Max (0902)$0.336Qwen3.8 Max Prime$0.672$0.00$0.20$0.40$0.60$0.80
Fresh inputVisible output

159,000 input + 3,000 visible output tokens per task. No cache discount; hidden reasoning excluded.

Qwen3.8 Max Prime costs $0.336 more per task.

Qwen3.8 Max (0902)$0.0042Qwen3.8 Max Prime$0.0084$0.00$0.005$0.01Qwen3.8 Max (0902)$0.0042Qwen3.8 Max Prime$0.0084$0.00$0.005$0.01
Fresh inputVisible output

1,500 input + 200 visible output tokens per task. No cache discount; hidden reasoning excluded.

Qwen3.8 Max Prime costs $0.0042 more per task.

Qwen3.8 Max (0902)$2.69Qwen3.8 Max Prime$5.37$0$2$4$6Qwen3.8 Max (0902)$2.69Qwen3.8 Max Prime$5.37$0$2$4$6
Fresh inputVisible output

1,315,500 input + 9,000 visible output tokens per task. No cache discount; hidden reasoning excluded.

Qwen3.8 Max Prime costs $2.69 more per task.

Qwen3.8 Max (0902)$4,905.60Qwen3.8 Max Prime$9,811.20$0$5,000$10,000Qwen3.8 Max (0902)$4,905.60Qwen3.8 Max Prime$9,811.20$0$5,000$10,000
Fresh inputVisible output

Assumption: 20 tasks/hour × 730 hours = 14,600 tasks/month.

Observed · United States

Wait and streaming speed

The same short request. Each route must have successful answers on at least two dates.

Qwen3.8 Max (0902)

Direct API · Alibaba Cloud · 110 answers on 22 dates.

First answer token 1.50 s
Observed range · dot = median0.01.02.03.04.0secondsObserved range · dot = median0.01.02.03.04.0seconds

Qwen3.8 Max (0902) · 1.50 s median; observed range 1.11 s–3.19 s.

Output speed 43.2 tokens/s
Observed range · dot = median020406080tokens/sObserved range · dot = median020406080tokens/s

Qwen3.8 Max (0902) · 43.2 tokens/s median; observed range 24.5 tokens/s–59.9 tokens/s.

Observed · independent medians

More output than the answer shows.

Visible answer560204060Visible answer560204060
Unknown · Hidden reasoning

The API did not report this count; Unknown is not zero.

Calculated median cost per request: $0.00108.

Visible outputHidden reasoning

Visible output and hidden reasoning are independent medians and are not added together. Request cost is the median of individually priced requests. Hidden reasoning is billed at the output rate.

Published context window: 1,000,000 tokens.

Qwen3.8 Max Prime

Collecting

No route for this model has passed the publication threshold.

Published context window: 1,000,000 tokens.

Unknown

No comparable published API documentation for this pair.

Sources: this page; published model prices (data (JSON)); task assumptions (data (JSON)). Published prices · Observed responses · Calculated scenarios · Assumptions stated with each chart.