Tool
API invoice auditor
Open the usage or cost export from OpenAI, Anthropic or OpenRouter, or your own table, to see what you paid, what the same tokens cost today at published prices, what the cheapest models of the same price class would charge for the same work, and where the money goes: cache, long requests, batch and short tasks on expensive models. In the worked example below, a sample week of Anthropic usage costs $496.75 at today’s prices; the cheapest models of the same price class would do the same work for $337.40.
Calculated Your files are read in this browser and are not uploaded. All calculators · Task cost calculator

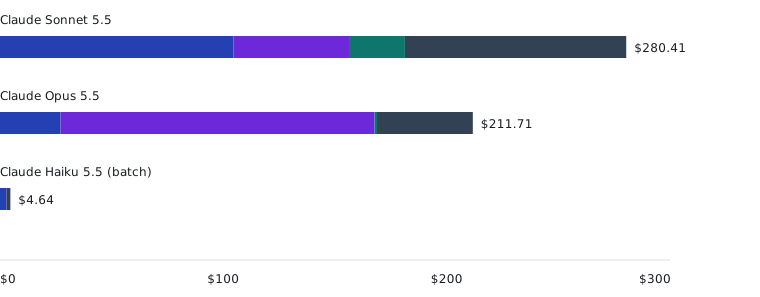
Worked example Calculated Anthropic usage and costs, sample numbers · data of 9 Nov 2026
- Today’s published price
- $496.75
- Paid, from your files
- $496.75
- Cheapest same-class models
- $337.40
119 records read, 3 models. Your files show $496.75 paid. At today’s published prices the same tokens cost $496.75. The cheapest models of the same price class would do the same work for $337.40 (−32%).
| Model in the file | Input tokens | Read from cache | Output tokens | Paid (file) | Today’s published price Published | Cheapest same-class model | Saving |
|---|---|---|---|---|---|---|---|
| claude-sonnet-5-5 · priced as Claude Sonnet 5.5 | 319,200,969 | 77.1% | 9,910,878 | $280.41 | $280.41 | — | — |
| claude-opus-5-5 · priced as Claude Opus 5.5 | 29,937,077 | 18.7% | 2,144,752 | $211.71 | $211.71 | GPT-6 Sol · $53.87 | $157.84 · −75% |
| claude-haiku-5-5 · priced as Claude Haiku 5.5 | 57,481,802 | 0% | 7,059,448 | $4.64 | $4.64 | GPT-6 Luna · $3.12 | $1.52 · −33% |
Same class: models from our comparisons whose standard L2 task costs within a factor of two of this model’s. Their token counts are converted with our measured tokenizer ratios for the kind of text you pick.
Where the money goes
- claude-sonnet-5-5: the same work through the batch API, where it can wait, would cost $140.20 less on uncached input and output at the batch price listed for Claude Sonnet 5.5. Our data has no batch price for cache or long-request tokens, so they are left out of this saving.
- claude-opus-5-5: the same work through the batch API, where it can wait, would cost $132.22 less on uncached input and output at the batch price listed for Claude Opus 5.5. Our data has no batch price for cache or long-request tokens, so they are left out of this saving.
- claude-opus-5-5: 17,576,678 tokens were written to the cache and only 5,589,570 read back. A cache write costs more than plain input, so prefixes that are not reused cost $70.31 extra.
- claude-sonnet-5-5: 77.1% of input was read from the cache. Each further 10 points of input served from the cache would save about $60.65 on this file (cache read $0.100 instead of $2.00 per 1M).
- claude-opus-5-5: 18.7% of input was read from the cache. Each further 10 points of input served from the cache would save about $11.38 on this file (cache read $0.200 instead of $4.00 per 1M).
- claude-haiku-5-5: 0% of input was read from the cache. Each further 10 points of input served from the cache would save about $0.517 on this file (cache read $0.010 instead of $0.100 per 1M).
- claude-sonnet-5-5: 38,593,506 tokens were in requests above 200,000 tokens; the long-request price for this model is not in our data, so they are priced at the standard rate.
Who served your OpenRouter requests
OpenRouter sends a request for a model to one of the providers that serve it, and providers charge different prices. These rows of your files name the provider.
| Model in the file | Provider | Requests | Tokens | Paid (file) |
|---|
What the report contains
## API spend review

119 records read, 3 models. Your files show $496.75 paid. At today’s published prices the same tokens cost $496.75. The cheapest models of the same price class would do the same work for $337.40 (−32%).

| Model | Tokens | Paid (file) | Today’s published price | Cheapest same-class model | Saving |
|---|---:|---:|---:|---|---:|
| claude-sonnet-5-5 | 329,111,847 | $280.41 | $280.41 | — | — |
| claude-opus-5-5 | 32,081,829 | $211.71 | $211.71 | GPT-6 Sol, $53.87 | $157.84 |
| claude-haiku-5-5 | 64,541,250 | $4.64 | $4.64 | GPT-6 Luna, $3.12 | $1.52 |

### Where the money goes

- claude-sonnet-5-5: the same work through the batch API, where it can wait, would cost $140.20 less on uncached input and output at the batch price listed for Claude Sonnet 5.5. Our data has no batch price for cache or long-request tokens, so they are left out of this saving.
- claude-opus-5-5: the same work through the batch API, where it can wait, would cost $132.22 less on uncached input and output at the batch price listed for Claude Opus 5.5. Our data has no batch price for cache or long-request tokens, so they are left out of this saving.
- claude-opus-5-5: 17,576,678 tokens were written to the cache and only 5,589,570 read back. A cache write costs more than plain input, so prefixes that are not reused cost $70.31 extra.
- claude-sonnet-5-5: 77.1% of input was read from the cache. Each further 10 points of input served from the cache would save about $60.65 on this file (cache read $0.100 instead of $2.00 per 1M).
- claude-opus-5-5: 18.7% of input was read from the cache. Each further 10 points of input served from the cache would save about $11.38 on this file (cache read $0.200 instead of $4.00 per 1M).
- claude-haiku-5-5: 0% of input was read from the cache. Each further 10 points of input served from the cache would save about $0.517 on this file (cache read $0.010 instead of $0.100 per 1M).
- claude-sonnet-5-5: 38,593,506 tokens were in requests above 200,000 tokens; the long-request price for this model is not in our data, so they are priced at the standard rate.

Prices: Measured Lab published-price data, version 2026.11.09-r1. Tokens as counted in the files; same-class models priced with our measured tokenizer ratios. Source: /tools/invoice-auditor/
How to export your usage
OpenAI
In the platform’s Usage dashboard, use Export and pick Activity data for tokens or Cost data for spend; group by model and choose CSV (OpenAI Help Center: export monthly usage details, read ). The Usage and Costs API return the same data as JSON: OpenAI API reference: Usage, completions, read ; OpenAI API reference: Costs, read . With Usage data the auditor knows the number of requests, which the short-task check needs.
Anthropic
The Console’s Usage and Cost pages each have a CSV export (Claude Help Center: Cost and usage reporting in the Console, read ). The Admin API usage report, grouped by model, service tier and context window, also tells which tokens were in requests above 200,000 tokens: Claude API reference: Messages usage report, read ; cost report: Claude API reference: Cost report, read .
OpenRouter
Activity can be exported as CSV, grouped by model (OpenRouter docs: Activity export, read ); the activity API returns the same as JSON with requests, cached tokens and spend in US dollars: OpenRouter API reference: activity, read .
The providers do not list the columns of their CSV exports, so the auditor reads the header row and lets you pick columns by hand when it does not recognise them.
What the auditor reads
JSON from the four usage and cost APIs above is recognised by its fields. In tables, case, spaces and dots in the header do not matter, and the first name found is used:
| What | Column names |
|---|---|
| Model | model, model_name, model_id, snapshot_id, model_permaslug, model_slug, permaslug, model_version |
| Input without cache | input_uncached_tokens, uncached_input_tokens, input_tokens_uncached, uncached_input |
| Input | input_tokens, prompt_tokens, tokens_prompt, n_context_tokens_total, context_tokens, input_token_count, input |
| Cache read | cache_read_input_tokens, input_cached_tokens, cached_tokens, n_cached_context_tokens_total, cache_read_tokens, cached_input_tokens, tokens_cached, native_tokens_cached, cache_read |
| Cache write | cache_creation_input_tokens, cache_write_input_tokens, cache_write_tokens, cache_creation_tokens; or cache_creation_ephemeral_5m_input_tokens, ephemeral_5m_input_tokens, input_cache_write_tokens; longer-lived writes: cache_creation_ephemeral_1h_input_tokens, ephemeral_1h_input_tokens, input_cache_write_12h_tokens |
| Output | output_tokens, completion_tokens, tokens_completion, n_generated_tokens_total, generated_tokens, output_token_count, output |
| Cost, US dollars | cost_usd, total_cost_usd, cost, total_cost, amount_usd, amount_value, amount, spend_usd, spend, cost_total; usage in OpenRouter data |
| Requests | num_model_requests, requests, request_count, num_requests, n_requests |
| Batch and context | batch, is_batch, service_tier, context_window |
What counts as input follows each provider’s documentation: OpenAI’s input count includes cached and cache-write tokens; Anthropic reports uncached input apart from cache reads and writes; OpenRouter’s cached tokens are generally part of the prompt tokens. Anthropic’s cost report gives amounts in cents, and the auditor converts them to dollars. Rows without a model name and total lines are set aside, and the result says how many.
Assumptions
| What | How it is counted |
|---|---|
| Price of a set of tokens | uncached input × input price + cache writes × write price + cache reads × read price + output × output price, per million tokens. |
| Cache and long requests | Cache prices and prices above a long-context threshold as the provider publishes them for the channel the model is priced on, the same as in the task cost calculator (read 9 Nov 2026): Aion 3.5, Aion 3.5 Mini, Aion-2.0, Aion-3.0, Aion-3.0-Mini, Beam 1.0 501B A23B, Claude Fable 5, Claude Fable 5.1, Claude Haiku 4.5, Claude Haiku 5.5, Claude Opus 4.1, Claude Opus 4.5, Claude Opus 4.6, Claude Opus 4.7, Claude Opus 4.8, Claude Opus 5, Claude Opus 5.5, Claude Sonnet 4.5, Claude Sonnet 4.6, Claude Sonnet 5, Claude Sonnet 5.5, Codestral 2508, Command A+, Cydonia 24B V4.1, DeepSeek V3 0324, DeepSeek V3.1, DeepSeek V3.2, DeepSeek V4 Flash 0423, DeepSeek V4 Flash 0731, DeepSeek V4 Flash Vision Exp, DeepSeek V4 Pro 0423, DeepSeek V4 Pro 0813, DeepSeek V4.1 Flash 0910, DeepSeek V4.1 Flash 1017, Devstral 2 2512, Ember-1, Fugu Max, Fugu Ultra, Fugu Ultra v2, GLM 4.5, GLM 4.5 Air, GLM 4.5V, GLM 4.6, GLM 4.6V, GLM 4.7, GLM 5, GLM 5 Turbo, GLM 5.1, GLM 5.2, GLM 5.3, GLM 5.3 Flash, GLM 5.3 FlashX, GLM 5.3 FlashX Legal, GLM 5.3 Prime, GLM 5V Turbo, GPT Chat Latest, GPT-4.1, GPT-4.1 Mini, GPT-4.1 Nano, GPT-4o, GPT-4o (2024-08-06), GPT-4o (2024-11-20), GPT-4o-mini, GPT-4o-mini (2024-07-18), GPT-5, GPT-5 Image, GPT-5 Image Mini, GPT-5 Mini, GPT-5 Nano, GPT-5.1, GPT-5.1-Codex, GPT-5.1-Codex-Max, GPT-5.1-Codex-Mini, GPT-5.2, GPT-5.2 Chat, GPT-5.2-Codex, GPT-5.3-Codex, GPT-5.4, GPT-5.4 Image 2, GPT-5.4 Nano, GPT-5.5, GPT-5.6 Luna, GPT-5.6 Luna Pro, GPT-5.6 Sol, GPT-5.6 Sol Pro, GPT-5.6 Terra, GPT-5.6 Terra Pro, GPT-6 Astra, GPT-6 Astra Pro, GPT-6 Luna, GPT-6 Luna Pro, GPT-6 Sol, GPT-6 Sol Pro, GPT-6.1 Sol, GPT-6.1 Sol Pro, GPT-6.1 Terra, GPT-6.1 Terra Pro, Gemini 2.5 Flash, Gemini 2.5 Flash Lite, Gemini 2.5 Pro, Gemini 2.5 Pro Preview 06-05, Gemini 3 Flash Preview, Gemini 3.1 Flash Lite, Gemini 3.1 Flash Lite Preview, Gemini 3.1 Pro Preview, Gemini 3.1 Pro Preview Custom Tools, Gemini 3.5 Flash, Gemini 3.5 Flash Lite, Gemini 3.6 Flash, Gemini 3.7 Flash, Gemini 3.8 Flash, Gemma 3 27B, Gemma 4 26B A4B , Glimpse, Granite 4.2 8B, Grok 4.20, Grok 4.20 Multi-Agent, Grok 4.3, Grok 4.5, Grok 4.6, Grok 4.7, Grok Build 0.1, Hermes 4 405B, Hy3, Hy3 preview, Hy4, Hy4 preview, Inkling, Inkling Small, Kimi K2 Thinking, Kimi K2.5, Kimi K2.6, Kimi K2.7 Code, Kimi K3, Kimi K3.1 Pro, LFM2.5-2.6B, LFM2.5-24B-A2B, LFM3-1.7B, Ling 3.0 Flash, Ling 3.0 Flash VL, Ling 3.0 Tiny, Ling 3.1 Flash, Llama 3.3 70B Instruct, Llama 4 Maverick, LongCat 2.0, Magnum v4 72B, Mercury 2, Mercury 2.5, Mercury 3, MiMo-V2.5, MiMo-V2.5-Pro, MiMo-V2.6-Flash, MiMo-V2.6-Pro, MiMo-V2.6-Pro-UltraSpeed, MiniMax M2.5, MiniMax M2.7, MiniMax M3.1 Flash, Ministral 3 14B 2512, Ministral 3 3B 2512, Ministral 3 8B 2512, Mistral Large, Mistral Large 2407, Mistral Large 3 2512, Mistral Large 4, Mistral Medium 3, Mistral Medium 3.1, Mistral Medium 3.5, Mistral Small 4, Mixtral 8x22B Instruct, Muse Glimmer 30B, Muse Spark 1.1, Muse Spark 1.2, Muse Spark 1.2 Contributor, Muse Spark 1.3, Muse Spark 1.3 Contributor, Muse Spark Open, Muse Wonder, Nano Banana (Gemini 2.5 Flash Image), Nano Banana Pro (Gemini 3 Pro Image Preview), Nano Banana Pro (Gemini 3 Pro Image), Nemotron 3 Nano 30B A3B, Nemotron 3 Ultra, Nemotron 3.5 Lightning, Nemotron 3.5 Super VL, Nex-N2.5-Mini, Nex-N2.5-Pro, Nova Premier 1.0, Pareto 26.10, Pareto 26.9, Particle-1, Qwen-Plus, Qwen2.5 VL 72B Instruct, Qwen3 235B A22B Instruct 2507, Qwen3 30B A3B Instruct 2507, Qwen3 Coder 480B A35B, Qwen3 Coder Flash, Qwen3 Coder Next, Qwen3 VL 235B A22B Instruct, Qwen3 VL 8B Instruct, Qwen3.5 397B A17B, Qwen3.5-35B-A3B, Qwen3.6 35B A3B, Qwen3.7 Flash, Qwen3.7 Max, Qwen3.7 Plus, Qwen3.8 2.4T A95B, Qwen3.8 Max Prime, Qwen3.8 Omni Flash, R1 0528, ReMM SLERP 13B, Ripple 65B Preview, Saba, Sakana Namazu, Schematron V2 Small, Schematron V2 Turbo, Skyfall 36B V2, Solar Mini 4, Solar Pro 4, Step 3.7 Flash, Step 5 Preview, Ternary Bonsai 2 27B, Ternary Bonsai 2 9B, UI-TARS 7B , Voxtral Small 24B 2507, Weaver (alpha), gpt-oss-safeguard-20b, o3. For a model without a published cache price, a file with cached tokens shows the price as Unknown, and such a model is not offered as a cheaper option for those tokens. Requests above 200,000 tokens are priced at the higher rate where the provider publishes one; otherwise at the standard rate, and the result says so. For such requests, a cheaper model is offered only when our data has its price for long requests. |
| Batch | Batch rows at the model’s batch price where our data has one; otherwise, and for cache tokens in batch rows, the price is Unknown. The batch saving counts uncached input and output only. |
| Same price class | Models from our comparisons whose L2 task, a 50,000-token document in three steps, costs within a factor of two of this model’s. |
| Tokens on another model | Converted with our measured ratio to o200k_base for the kind of text you pick (see the token counter); without a measured ratio, as counted in the file. |
| Short tasks Assumption | On average up to 4,000 input and 500 output tokens per request, with a model of the same provider at least four times cheaper on the L2 task. |
| Cache saving | The price of moving 10 percentage points of input from plain input to cache reads. |
| Currency | US dollars. A table’s cost column counts as dollars when its name says USD, and in OpenRouter data. |
Quality differs between models; the auditor compares prices for the same work and leaves the choice to you. The task cost calculator prices whole tasks with the same data; the methodology explains how prices are read.